
What Is Deep Learning?
Deep learning is a branch of artificial intelligence that uses artificial neural networks to recognize patterns, learn from data, and make predictions. It helps computers perform tasks such as understanding speech, recognizing images, and processing human language. Unlike traditional programming, deep learning systems can learn useful patterns from examples instead of relying entirely on manually written rules.
Deep learning is a specialized area of machine learning, which focuses on teaching computers to improve their performance using data. Its defining feature is the use of neural networks with multiple processing layers. These layers gradually transform information into representations that help the system identify relationships, classify information, and generate useful outputs.
Understanding deep learning basics for beginners does not require advanced programming knowledge at the beginning. The most important concepts include neural networks, training data, algorithms, and model predictions. Once you understand how these elements work together, learning more advanced topics becomes easier and helps you recognize how artificial intelligence influences everyday technology.
How Does Deep Learning Work?
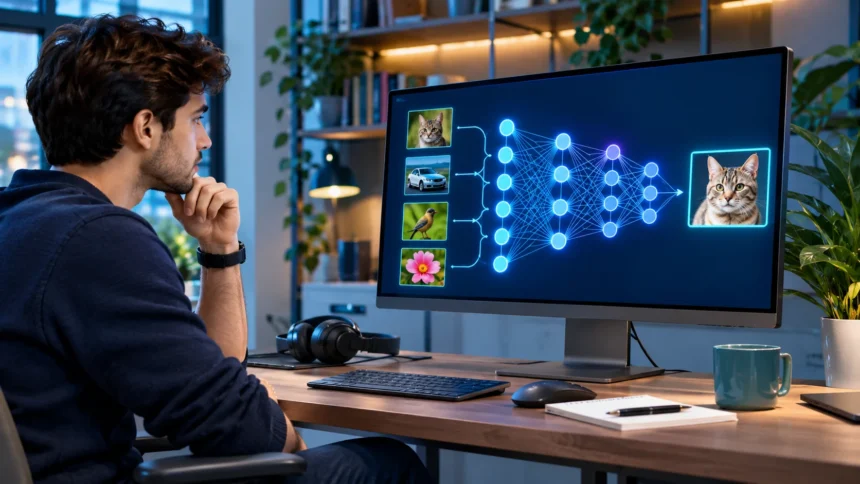
Deep learning works by processing information through interconnected layers of artificial neurons. Each layer receives numerical inputs, performs mathematical operations, and passes the results to the next layer. As information moves through the network, the model can identify increasingly complex patterns that support predictions, classifications, or other tasks.
For example, an image recognition system may first learn to identify simple visual features such as edges and colors. Later layers can combine these features into more complex shapes and objects. Through repeated training, the network adjusts its internal parameters to improve its ability to recognize similar patterns in unfamiliar images.
The learning process involves comparing model predictions with expected outcomes and measuring the difference using a loss function. An optimization algorithm then updates the network’s parameters to reduce prediction errors. Repeating this process across training examples gradually improves the model, although successful learning depends on data quality, architecture, and suitable training methods.
Understanding Artificial Neural Networks
Artificial neural networks are computing systems inspired loosely by the way biological neurons process information. They consist of interconnected computational units arranged into layers that transform incoming data. These networks form the foundation of deep learning and enable computers to model complex relationships that may be difficult to describe using conventional programming rules.
A typical neural network contains an input layer, one or more hidden layers, and an output layer. The input layer receives information, while hidden layers perform mathematical transformations that help identify patterns. The output layer produces a result, such as a predicted category, a numerical value, or another form of processed information.
Each connection in a neural network has a numerical weight that influences how information moves through the system. During training, these weights are adjusted to improve predictions. Understanding weights, layers, and activation functions provides a useful foundation for exploring more advanced deep neural network concepts without becoming overwhelmed by technical terminology.
Difference Between Artificial Intelligence, Machine Learning, and Deep Learning
Artificial intelligence is the broad field of developing computer systems capable of performing tasks associated with human intelligence. These tasks may include reasoning, language processing, planning, and decision-making. AI includes several approaches, ranging from traditional rule-based systems to advanced statistical models and neural networks trained on large datasets.
Machine learning is a subset of artificial intelligence that enables systems to identify patterns and improve through experience with data. Instead of manually defining every rule, developers train algorithms using examples. Common machine learning methods include decision trees, linear regression, support vector machines, and neural networks.
Deep learning is a specialized branch of machine learning that relies on multilayer neural networks. It is particularly useful for working with images, audio, text, and other complex information. Understanding the relationship between AI, machine learning, and deep learning helps beginners recognize why these terms are connected but should not be used interchangeably.
Types of Deep Learning Neural Networks
Different neural network architectures are designed to handle different kinds of information and computational tasks. Some models specialize in recognizing visual patterns, while others process sequences or generate new content. Learning about these architectures helps beginners understand why developers choose particular deep learning methods for specific applications.
Convolutional neural networks, commonly called CNNs, are widely associated with computer vision tasks. They use specialized operations to identify spatial patterns within images and other structured data. Recurrent neural networks, or RNNs, process sequential information and have historically been used for language modeling, speech processing, and time-series analysis.
Transformers are another important architecture, especially in modern natural language processing and generative artificial intelligence. They use attention mechanisms to model relationships between different elements of information. Other architectures include autoencoders and generative adversarial networks, which support applications such as representation learning, anomaly detection, and synthetic data generation.
What Is Training Data in Deep Learning?
Training data refers to the examples used to teach a deep learning model how to recognize patterns or perform tasks. Depending on the application, these examples may include images, written documents, audio recordings, numerical measurements, or videos. The quantity, relevance, and quality of training data strongly influence model performance.
For instance, an image classification model designed to recognize animals needs examples representing different animal categories. These images should ideally include varied backgrounds, lighting conditions, and appearances. A diverse dataset helps the model learn useful characteristics rather than relying on accidental similarities that may not appear in real-world situations.
Training datasets may contain labels that identify correct answers or consist of unlabeled information used in other learning approaches. Developers often divide data into training, validation, and test sets to evaluate performance. This separation helps identify whether a model has learned meaningful patterns or simply memorized examples from its training dataset.
How Deep Learning Models Learn From Data
Deep learning models learn by repeatedly processing training examples and adjusting their internal parameters. During each training step, the network produces an output based on its current weights. A mathematical loss function measures how closely that output matches the training objective, providing feedback about the model’s performance.
Backpropagation is a widely used technique for calculating how individual network parameters contribute to prediction errors. Optimization algorithms, such as stochastic gradient descent or Adam, use this information to update the model. These adjustments are repeated across many batches of examples until training reaches a suitable stopping point.
Learning does not guarantee that a model will perform correctly on unfamiliar information. A system might memorize training examples without understanding patterns that generalize to new situations. Developers address this problem through careful evaluation, appropriate regularization, varied datasets, and adjustments to model architecture and training procedures.
Supervised, Unsupervised, and Self-Supervised Learning
Supervised learning uses labeled examples to teach models the relationship between inputs and expected outputs. For example, a system might learn to classify emails as spam or legitimate messages using previously labeled data. This approach is common in image classification, medical image analysis, and many prediction tasks.
Unsupervised learning uses data without predefined answer labels to discover useful patterns or representations. Techniques may identify similarities, group related information, or reduce the complexity of datasets. Deep learning approaches such as autoencoders can support unsupervised representation learning by finding compact descriptions of input information.
Self-supervised learning creates training objectives from the structure of the data itself. For example, a language model may learn by predicting missing or subsequent tokens in text. This approach has become important in modern deep learning applications because it allows large models to learn from extensive collections of information without requiring manual labels for every example.
Deep Learning Algorithms Explained Simply
A deep learning algorithm is a mathematical procedure used to train or operate a neural network. These procedures determine how models process information, calculate errors, and adjust their internal parameters. While the underlying mathematics can become complicated, beginners can understand the main ideas without immediately studying every equation.
Gradient descent is one of the fundamental optimization concepts behind neural network training. It updates model parameters in directions expected to reduce a chosen loss function. Variants such as stochastic gradient descent and Adam offer different methods for managing updates, training stability, and computational efficiency.
Activation functions are another essential component because they introduce nonlinearity into neural networks. Without nonlinear transformations, stacking ordinary linear layers would not provide the same ability to represent complex patterns. Common activation functions include ReLU, sigmoid, and tanh, each offering different mathematical properties and practical advantages.
Common Real-World Applications of Deep Learning
Deep learning supports many technologies people interact with regularly, including voice assistants, recommendation systems, and image recognition tools. Speech recognition software can convert spoken language into written text, while computer vision models help identify objects in photographs. These applications demonstrate how neural networks transform complex information into useful predictions and outputs.
Healthcare researchers use deep learning to analyze medical images, recognize patterns, and support certain diagnostic workflows. Financial organizations explore neural networks for fraud detection, risk analysis, and transaction monitoring. In transportation, deep learning contributes to computer vision and perception systems used in driver-assistance technologies and autonomous vehicle research.
Generative AI is another major application involving deep learning models trained to produce text, images, audio, and other content. These systems can assist with writing, coding, design, and information processing. However, generated outputs may contain errors, so human review remains important when accuracy, safety, or reliability matters.
Benefits of Deep Learning Technology
One important advantage of deep learning is its ability to identify complicated relationships within large datasets. Traditional approaches often require developers to manually design features before training a model. Deep neural networks can learn useful representations automatically, making them effective for tasks involving complex visual, linguistic, and auditory information.
Deep learning models can also achieve strong performance in specific applications when trained with suitable data and computational resources. Their flexibility allows researchers to adapt neural network architectures to many different problems. Transfer learning further improves efficiency by allowing developers to build on models that have already learned useful patterns.
Another benefit is the potential to automate repetitive information-processing tasks and support human decision-making. Image classification, document analysis, and speech transcription are examples where automation can save time. Nevertheless, successful implementation requires careful evaluation because high performance on training data does not automatically translate into reliable real-world results.
Challenges and Limitations of Deep Learning
Despite its capabilities, deep learning presents several technical and practical challenges. Training large neural networks may require significant computational power, specialized hardware, and substantial energy consumption. These requirements can make advanced projects expensive, particularly for individuals or organizations with limited computing resources and technical experience.
Data quality is another major concern because neural networks learn patterns from the information used during training. Incomplete, inaccurate, or unrepresentative datasets can produce unreliable predictions. Models may also reproduce harmful biases found in their training data, making fairness, privacy, and responsible data collection important considerations.
Deep learning systems can sometimes behave unpredictably when encountering unfamiliar situations or unusual inputs. Their decisions may also be difficult to explain because many internal computations interact in complex ways. Understanding these limitations of deep learning helps beginners develop realistic expectations and recognize the importance of testing, monitoring, and human oversight.
Programming Languages and Tools Used in Deep Learning
Python is one of the most widely used programming languages for deep learning because of its readable syntax and extensive software ecosystem. Many researchers and developers use Python to prepare datasets, train neural networks, and evaluate results. Its broad collection of learning resources also makes it accessible to beginners exploring artificial intelligence programming.
PyTorch and TensorFlow are popular frameworks that provide tools for building and training neural networks. They support automatic differentiation, tensor operations, and hardware acceleration for computationally demanding workloads. Keras offers a high-level interface that can simplify model development, making it useful for people learning the basics.
Beginners may also encounter tools such as Jupyter Notebook, Google Colab, NumPy, and Matplotlib during their learning journey. These applications support interactive coding, numerical calculations, visualization, and experimentation. Starting with a simple development environment allows learners to focus on understanding model behavior before managing more complicated technical infrastructure.
How to Start Learning Deep Learning as a Beginner
Starting with basic Python programming is a practical first step toward understanding deep learning. Focus on variables, functions, loops, and common data structures before exploring machine learning libraries. These fundamental skills make it easier to read example programs and understand how information moves through neural network training workflows.
Next, develop a basic understanding of essential mathematical ideas such as vectors, matrices, probability, and derivatives. You do not need to master advanced mathematics immediately, but familiarity with these concepts improves understanding. Learning how neural networks calculate predictions and update weights helps connect programming exercises with the principles behind deep learning.
Once the fundamentals feel comfortable, experiment with small datasets and beginner-friendly neural network examples. Image classification and simple numerical prediction projects provide opportunities to practice training and evaluation. Gradually increase project complexity while reviewing mistakes, comparing model results, and building confidence through practical experience.
Simple Deep Learning Project Ideas for Beginners
A handwritten digit recognition project is an excellent introduction to neural network training. Beginners can use the MNIST dataset, which contains images of handwritten digits, to build a simple classification model. This project demonstrates important concepts such as input preparation, network layers, training loops, and prediction accuracy.
Another beginner-friendly idea involves classifying clothing images using the Fashion-MNIST dataset. A model learns to distinguish categories such as shirts, trousers, shoes, and bags from grayscale images. Comparing predictions with actual labels helps learners understand model evaluation, common errors, and the challenges of recognizing visually similar categories.
Text classification is also useful for understanding natural language processing with deep learning. Beginners can experiment with identifying positive and negative sentiment in short reviews using a small labeled dataset. These projects provide practical experience while introducing techniques that connect directly with more advanced language models and artificial intelligence applications.
Deep Learning vs Traditional Machine Learning
Traditional machine learning methods often perform well on structured datasets containing clearly defined numerical or categorical features. Algorithms such as decision trees and logistic regression can be efficient and relatively easy to interpret. They are commonly used for prediction problems where available data is limited or computational resources are restricted.
Deep learning becomes particularly useful when working with complex unstructured information such as images, audio, and natural language. Neural networks can automatically learn representations that would otherwise require extensive manual feature engineering. However, these advantages often depend on sufficient data, appropriate model design, and greater computational resources.
Choosing between traditional machine learning and deep learning depends on the problem rather than following current technology trends. Simple models may provide comparable or better results for certain tasks while remaining easier to maintain. Beginners should understand both approaches because selecting an appropriate method is an important part of effective machine learning development.
Future of Deep Learning and Artificial Intelligence
The future of deep learning will likely involve continued improvements in model efficiency, reliability, and practical capabilities. Researchers are developing methods that reduce computational requirements while maintaining useful performance. Advances in specialized hardware, model compression, and training techniques may make sophisticated neural networks more accessible to smaller organizations and individual developers.
Multimodal artificial intelligence is another important research direction because it combines different forms of information within related systems. These models may process text, images, audio, and video to perform more complex tasks. Improved multimodal capabilities could support applications in education, accessibility, scientific research, and human-computer interaction.
Responsible development will remain essential as deep learning becomes more widely integrated into everyday technology. Researchers and policymakers continue examining questions involving transparency, privacy, fairness, and safety. Beginners who combine technical understanding with awareness of these challenges will be better prepared to evaluate and develop trustworthy artificial intelligence systems.
Conclusion
Deep learning is an important area of artificial intelligence that enables computers to learn complex patterns from data. Its foundation includes artificial neural networks, training algorithms, and mathematical methods used to improve predictions. Understanding these core concepts provides beginners with a useful starting point for exploring modern machine learning technologies.
From image recognition and speech processing to generative AI, deep learning supports numerous applications across different industries. However, successful systems require suitable data, careful training, and reliable evaluation. Learning about both the advantages and limitations helps beginners understand where neural networks provide value and where simpler approaches may be more appropriate.
The best way to learn deep learning is to combine fundamental knowledge with small practical projects. Begin with Python, explore neural network concepts, and gradually experiment with real datasets. Consistent practice and curiosity will help you develop the skills needed to understand more advanced artificial intelligence techniques over time.
Frequently Asked Questions
What is deep learning in simple words?
Deep learning is a type of machine learning that uses multilayer artificial neural networks to learn patterns from data. It helps computers recognize images, understand language, and make predictions through repeated training.
Is deep learning difficult for beginners?
Deep learning can seem challenging because it involves mathematics, programming, and neural networks. However, beginners can start with simple concepts, basic Python skills, and small projects before exploring advanced techniques.
What is the difference between machine learning and deep learning?
Machine learning includes various algorithms that learn patterns from data. Deep learning is a specialized type of machine learning that uses neural networks with multiple layers to process complex information.
Do I need to know Python to learn deep learning?
Python is not strictly required, but it is one of the most practical languages for learning deep learning. Its accessible syntax and popular frameworks make experimentation and model development easier.
What are some examples of deep learning?
Common examples include facial recognition technology, speech transcription, image classification, language translation, and generative AI systems. These applications use neural networks to identify relationships and process complex information.