
As Artificial Intelligence technology evolves, machine learning development has shifted from algorithm design to data quality. While building advanced AI architectures is easier than ever, training models to perform reliably in complex real-world environments remains a major challenge.
To overcome model hallucinations and edge-case errors, global tech enterprises require high-precision datasets. Partnering with a specialized vendor for data annotation ukraine like Technolex provides AI developers with the specialized human oversight needed to refine raw data. Technolex delivers end-to-end data preparation pipelines, deploying native linguists and technical annotators who label complex text, audio, and visual assets with exceptional accuracy.
The Hidden Operational Bottlenecks of AI Training Data
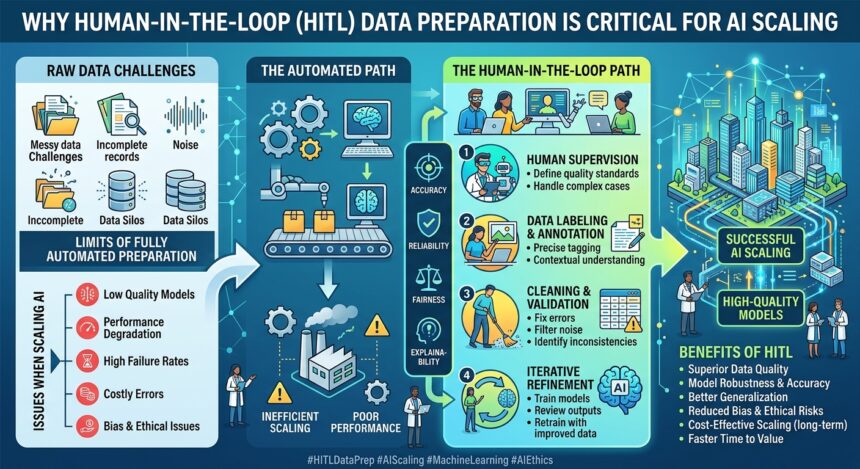
Rushing AI models to production using uncurated datasets or low-cost crowdsourcing leads to severe post-launch issues:
- Model Drift and Accuracy Degradation: Datasets containing inconsistent labeling cause models to generate inaccurate predictions, eroding user trust in customer-facing applications.
- Contextual and Linguistic Biases: Automated data scraping gathers noisy content. Without expert human evaluation, Large Language Models routinely miss regional dialects and domain-specific jargon.
- High Maintenance Costs: Retraining a flawed neural network post-deployment costs significantly more than investing in structured data annotation from the very beginning.
To build trustworthy AI applications, industry leaders rely on Data-Centric AI workflows that prioritize precise, human-verified data over sheer volume.
Scaling AI Pipelines with Technolex Expertise
To accelerate AI development cycles, technology companies need scalable annotation pipelines tailored to their specific technical requirements.
Technolex combines rigorous quality assurance with specialized domain expertise to support advanced AI models. Whether you are training conversational chatbots, voice recognition systems, or sentiment analysis tools, Technolex provides RLHF validation, custom dataset collection, and multi-stage text annotation. This comprehensive approach guarantees that your training data meets strict performance standards before deployment.
Conclusion
Sustained competitive advantage in the AI landscape belongs to companies that train algorithms on clean, ethically sourced data. By moving away from unverified crowdsourcing and partnering with an established data annotation provider like Technolex, businesses can deploy reliable AI products that earn customer trust and scale globally.